Capa oculta insuficiente
One hidden unit limits the available decision boundaries.
Entrenamiento real en el navegadorExperimento educativo local, sin API externa. Los datos sintéticos no son mediciones de producción.
Study guide & lesson outline
LEARNING CONTRACTUnderstand → implement → investigate
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
- Understand: state assumptions, shapes/units and a counterexample.
- Implement: reproduce a numerical example and inspect boundaries.
- Investigate: compare one alternative under a matched budget.
02 · Predice y configura
Las notas técnicas, los parámetros y las respuestas están actualmente en inglés.
03 · Analiza la evidencia
Métodos y referencias
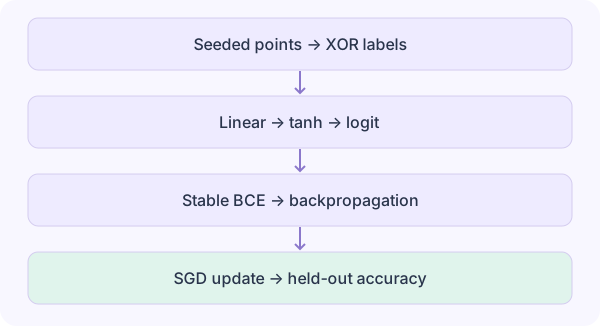
Actual full-batch gradient descent in JavaScript. 2 inputs → tanh hidden layer → sigmoid. Binary cross-entropy; 100 synthetic training and 100 held-out samples from the same generator. Held-out accuracy is not real-world generalization.
Text / 原始公式
h=tanh(Wx+b); p=σ(vᵀh+c); L=−mean[y log p+(1−y)log(1−p)]
Training convergence on tiny synthetic data does not imply an LLM can train in the browser.
Dive into Deep Learning · multilayer perceptrons ↗Preguntas de práctica
neural-2 / 01What does “Underpowered hidden layer” test?
One hidden unit limits the available decision boundaries.
Original teaching answer / local derivation. Method reference: Dive into Deep Learning · multilayer perceptrons ↗
Abrir laboratorio →neural-2 / 02Which computation produces the result in “Underpowered hidden layer”?
Original teaching answer / local derivation. Method reference: Dive into Deep Learning · multilayer perceptrons ↗
Abrir laboratorio →neural-2 / 03What is the baseline configuration for “Underpowered hidden layer”?
{"rate":0.3,"hidden":1,"epochs":1000,"task":0,"seed":42}
Original teaching answer / local derivation. Method reference: Dive into Deep Learning · multilayer perceptrons ↗
Abrir laboratorio →neural-2 / 04What numerical result should you check for “Underpowered hidden layer”?
Run the seeded training lab and inspect the actual loss and accuracy; convergence is not assumed.
Original teaching answer / local derivation. Method reference: Dive into Deep Learning · multilayer perceptrons ↗
Abrir laboratorio →neural-2 / 05How would you run a controlled comparison for “Underpowered hidden layer”?
Keep the supplied fixture and other settings fixed; change rate. Watch train loss, held-out accuracy and decision boundary over epochs.
Original teaching answer / local derivation. Method reference: Dive into Deep Learning · multilayer perceptrons ↗
Abrir laboratorio →neural-2 / 06What failure could invalidate a conclusion from “Underpowered hidden layer”?
Training convergence on tiny synthetic data does not imply an LLM can train in the browser.
Original teaching answer / local derivation. Method reference: Dive into Deep Learning · multilayer perceptrons ↗
Abrir laboratorio →neural-2 / 07Is “Underpowered hidden layer” a benchmark of a deployed language model?
No. Actual full-batch gradient descent in JavaScript. 2 inputs → tanh hidden layer → sigmoid. Binary cross-entropy; 100 synthetic training and 100 held-out samples from the same generator. Held-out accuracy is not real-world generalization.
Original teaching answer / local derivation. Method reference: Dive into Deep Learning · multilayer perceptrons ↗
Abrir laboratorio →neural-2 / 08Which evidence should you report for “Underpowered hidden layer”?
Watch train loss, held-out accuracy and decision boundary over epochs. Export inputs, engine, result and method; distinguish synthetic fixtures from observed production data.
Original teaching answer / local derivation. Method reference: Dive into Deep Learning · multilayer perceptrons ↗
Abrir laboratorio →neural-2 / 09How can another researcher reproduce “Underpowered hidden layer”?
Open neural-2, reset the preset, retain the exact inputs and run. Retain the seed, training epochs and all weights.
Original teaching answer / local derivation. Method reference: Dive into Deep Learning · multilayer perceptrons ↗
Abrir laboratorio →neural-2 / 10What is the next validation step after “Underpowered hidden layer”?
Training convergence on tiny synthetic data does not imply an LLM can train in the browser. Test the hypothesis on a representative held-out workload and document a baseline, success metric and stopping rule before claiming deployment readiness.
Original teaching answer / local derivation. Method reference: Dive into Deep Learning · multilayer perceptrons ↗
Abrir laboratorio →Assumptions, implementation & acceptance
XOR labels are 1 exactly when the signs differ. Stable logits BCE is max(z,0)−zy+log1p(exp(−|z|)); its logit gradient is sigmoid(z)−y. Training and held-out sets are separately seeded samples, not real-world validation.
Engine formulas, scenario presets and numerical safeguards reviewed. Seeded synthetic inputs are not a production benchmark.
Before running: predict a boundary case
One hidden unit limits the available decision boundaries.
Hint: isolate the assumption
Keep the baseline input fixed, change one parameter or boundary, and compare both the numerical result and the claimed units. A passing example verifies this fixture only.
Minimal executable example
Save the example and linked modules in one folder. Use Node.js 22 or newer, then run node neural-2.mjs. No third-party runtime dependencies.
import {calculate,network} from './academy-core.mjs';
const params={
  "rate": 0.3,
  "hidden": 1,
  "epochs": 1000,
  "task": 0,
  "seed": 42
};
const result=network(params).step(params.epochs);
console.log(result.metrics);Test and transfer
One hidden unit limits the available decision boundaries.
Record input, code version, expected result and observed result in the notebook below. Then construct a counterexample that violates the assumption above and explain why the original conclusion no longer follows.
Download complete kit (.tar.gz) · Complete reference kit and regression checksPredict, test and keep evidence
Before revealing an answer, predict one result. After the exercise, record the discrepancy and a transfer test. Saved locally across language editions.
Open notebook / export / clear →The mathematical review scope is recorded per lesson. It does not establish empirical paper reproduction; report suspected errors in your notes. Review scope