1. Why is entropy constant in supervised cross-entropy minimization?
Ver respuesta y criterios
The target distribution is fixed with respect to model parameters; the prediction distribution changes.
Understand entropy, cross-entropy, both KL directions and support mismatch.
Cálculos locales y ejemplos sintéticos. Sin API de pago ni benchmark de modelos reales.El contenido técnico está disponible en inglés y chino; esta versión usa el texto técnico en inglés.
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
Requisitos previos · Discrete probabilities, logarithms, expectations.
For fixed target P, minimizing cross-entropy minimizes forward KL because H(P) is constant. Reversing KL changes which distribution weights the penalty. Inputs are weights normalized to sum to one; all outputs use nats.
H(P) = −Σ pᵢ ln pᵢ
H(P,Q) = −Σ pᵢ ln qᵢ
KL(P||Q) = H(P,Q) − H(P)
JS(P,Q) = [KL(P||M)+KL(Q||M)]/2, M=(P+Q)/2
Common pitfall: Changing temperature at inference is not automatically calibration: fit and validate against labeled held-out data.
What is the entropy of a uniform distribution over 4 categories, in nats?
−4 × 0.25 × ln(0.25) = ln(4) ≈ 1.386294
Set
Deliver: input configurations, exported results, controlled variables, observations, alternative explanations and the next validation step.
A positive pᵢ at
Ejecuta el experimento para ver la evidencia.
Compara ejecuciones con variables controladas. Las exportaciones incluyen entradas y métodos.
Autoevaluación: explica el mecanismo, identifica los supuestos y propone una prueba. Sin calificación automática por LLM.
The target distribution is fixed with respect to model parameters; the prediction distribution changes.
Yes. It can confidently concentrate mass on the wrong class. Evaluate accuracy, calibration and task costs separately.
The expectation and support penalties change. Statements about mode coverage depend on the approximating family and target, not just a slogan.
This compares categorical distributions, not empirical model calibration. Calibration also needs predictions paired with observed outcomes; entropy alone is not correctness.
arXiv:1706.04599 · 2017
Guo et al. · Year denotes first arXiv submission
Read: Reliability diagrams, calibration metrics, temperature scaling.
Reading checkpoint: Distinguish class ranking from confidence quality; fit temperature on validation data, never the final test set.
@misc{arxiv170604599,
  title = {On Calibration of Modern Neural Networks},
  year = {2017},
  eprint = {1706.04599},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/1706.04599}
}
arXiv:2305.18290 · 2023
Rafailov et al. · Year denotes first arXiv submission
Read: KL-constrained reward objective, policy reparameterization and preference loss.
Reading checkpoint: Identify the reference-policy log ratio and β. The current information lab teaches KL, not a DPO trainer.
@misc{arxiv230518290,
  title = {Direct Preference Optimization: Your Language Model is Secretly a Reward Model},
  year = {2023},
  eprint = {2305.18290},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2305.18290}
}This compares categorical distributions, not empirical model calibration. Calibration also needs predictions paired with observed outcomes; entropy alone is not correctness.
Objective, derivatives, worked examples and implementation reviewed. A passing finite-difference or manifest check is not a paper reproduction certificate.
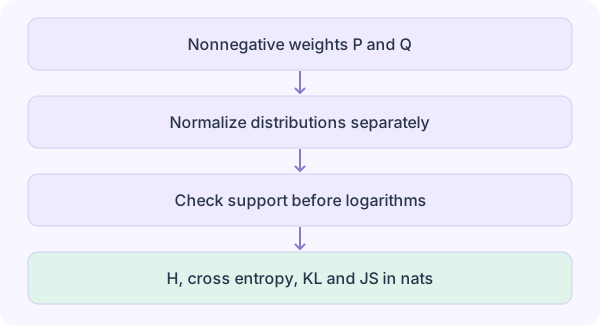
Set
Keep the baseline input fixed, change one parameter or boundary, and compare both the numerical result and the claimed units. A passing example verifies this fixture only.
Save the example and linked modules in one folder. Use Node.js 22 or newer, then run node information-theory.mjs. No third-party runtime dependencies.
import {runPhd} from './phd-core.mjs';
const params={
  "p": "0.7,0.2,0.1",
  "q": "0.5,0.3,0.2"
};
console.log(runPhd('information-theory',params));Set
Record input, code version, expected result and observed result in the notebook below. Then construct a counterexample that violates the assumption above and explain why the original conclusion no longer follows.
Download complete kit (.tar.gz) · Complete reference kit and regression checksBefore revealing an answer, predict one result. After the exercise, record the discrepancy and a transfer test. Saved locally across language editions.
Open notebook / export / clear →The mathematical review scope is recorded per lesson. It does not establish empirical paper reproduction; report suspected errors in your notes. Review scope