Understand: state assumptions, shapes/units and a counterexample.
Implement: reproduce a numerical example and inspect boundaries.
Investigate: compare one alternative under a matched budget.
Mechanism & assumptions
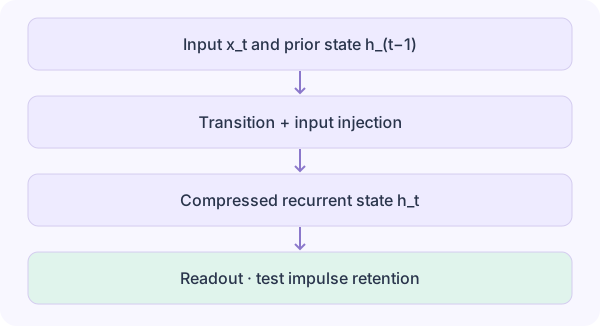
Mamba makes parts of a state-space update depend on the input, allowing selective retention and forgetting. A recurrent state summarizes history rather than storing all token keys and values. This changes memory and execution trade-offs, but does not establish universal superiority on retrieval or reasoning. The scalar recurrence below illustrates the idea only: it omits discretization, projections and the hardware-aware scan of the real architecture. Distinguish sequential decoding from parallel training and compare equal precision, batch and sequence lengths.
Text / 原始公式
h_t = a_t h_(t−1) + b_t x_t
y_t = c_t h_t
Historical contribution of h_0 = (Π_t a_t)h_0
[scalar teaching recurrence, not the full Mamba layer]
Worked example
With , ,0,3], ,0.5,0.1] and , states are [2,1,3.1]. The last low retention coefficient suppresses previous history. With constant , an initial signal retains 0.9^10≈0.3487 after ten updates; with it retains about 0.000977. Finite compressed state therefore creates an information-retention problem, not just a speed advantage.
Implementation exercise
Implement the scalar recurrence and inject a marker followed by distractors. Sweep retention, distractor count and state dimension. For a real-model study, compare delayed recall and associative retrieval with matched parameter/data budgets; separately record decode memory, throughput and accuracy. Do not treat a scalar recurrence result as a trained Mamba benchmark.
Deliver code, fixed seeds, raw results and one counterexample. These are experiment specifications, not executed GPU benchmarks.
Does constant decode state imply perfect long-context memory?
No. Fixed state compresses history. Capacity, dynamics and training determine which information survives. Test retrieval with controlled distances and distractors rather than extrapolating from asymptotic complexity.
Original teaching examples; sources checked October 2026. These are foundational mechanisms relevant to engineering, not a claim to cover every latest model.
A scalar recurrence illustrates state compression, not the full selective SSM architecture. State size and numerical discretization matter; linear recurrence is not equivalent to unrestricted attention retrieval.
Formula conditions, units and worked arithmetic reviewed. The implementation isolates one numerical mechanism; it does not train a policy or control real hardware.
Mechanism map: follow the transformations from top to bottom.
Before running: predict a boundary case
Impulse memory decays geometrically; preserves it and |a|>1 amplifies it.
Hint: isolate the assumption
Keep the baseline input fixed, change one parameter or boundary, and compare both the numerical result and the claimed units. A passing example verifies this fixture only.
Minimal executable example
Save the example and linked modules in one folder. Use Node.js 22 or newer, then run node selective-state-spaces.mjs. No third-party runtime dependencies.
Impulse memory decays geometrically; preserves it and |a|>1 amplifies it.
Record input, code version, expected result and observed result in the notebook below. Then construct a counterexample that violates the assumption above and explain why the original conclusion no longer follows.
Before revealing an answer, predict one result. After the exercise, record the discrepancy and a transfer test. Saved locally across language editions.
The mathematical review scope is recorded per lesson. It does not establish empirical paper reproduction; report suspected errors in your notes. Review scope