GRPO, verifiable rewards & reasoning
See how an outcome signal can reinforce successful solution behavior.
Study guide & lesson outline
LEARNING CONTRACTUnderstand → implement → investigate
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
- Understand: state assumptions, shapes/units and a counterexample.
- Implement: reproduce a numerical example and inspect boundaries.
- Investigate: compare one alternative under a matched budget.
Understand the mechanism
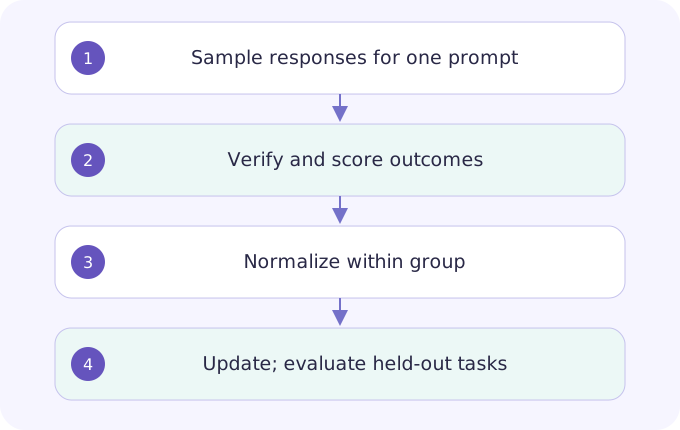
For a prompt, sample a group of responses and compare their rewards. Group-relative normalization can form advantage estimates without a separate learned value model in the discussed setup. Verifiable rewards, such as executable tests or exact mathematical checks, can provide scalable feedback, but only within what the verifier actually tests. Distinguish R1-Zero’s setup from R1’s multistage training.
Text / 原始公式
Âᵢ=(rᵢ−mean(r_group))/(std(r_group)+ε)
Training reward ≠ independent held-out capability
Equal rewards → zero centered signal
Mechanism map & worked derivation
| Symbol | Meaning |
|---|---|
| rᵢ | Reward of response i in the sampled group |
| μ, σ | Group mean and stated standard-deviation convention |
| Âᵢ | Relative normalized signal, not an absolute quality score |
- For [0,0,1,1],
and population Centering and scaling give [−1,−1,1,1], ignoring the tiny stabilizer. - Changing the last reward to 2 gives
and ≈0.829156. Relative advantages become approximately [−0.904534,−0.904534,0.301511,1.507557]. - If every reward equals 1, centering makes every numerator zero. Adding ε prevents division by zero but does not create learning contrast. Audit reward saturation and group diversity.
Document verifier behavior and false positives. More reasoning tokens or reward are not independent proof of better reasoning.
Change one variable. Explain what moves.
Original teaching calculation, not a reproduction of the paper’s benchmark. Bars are relative within this panel; numeric values and units are authoritative.
Original exercise & analysis
Normalize rewards [0,0,1,1]: advantages are approximately [−1,−1,1,1]. Then use [1,1,1,1]; no within-group contrast remains. Build a verifier adversary that passes formatting checks but returns a wrong answer, and add an independent correctness check.
Longer reasoning traces are not a capability metric. Control test-time tokens, sampling count and verifier leakage before attributing gains to training.
Does RL create new reasoning skills or elicit existing ones?
A benchmark gain alone cannot decide. Compare matched-compute base and trained models, analyze coverage of successful trajectories and test genuinely held-out tasks. State the narrower claim supported by evidence.