Prompt diff & token impact
Compare two prompt versions line by line and measure their token and UTF-8 byte changes.
Study guide & lesson outline
LEARNING CONTRACTUnderstand → implement → investigate
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
- Understand: state assumptions, shapes/units and a counterexample.
- Implement: reproduce a numerical example and inspect boundaries.
- Investigate: compare one alternative under a matched budget.
01Configure
02Add your input
Choose settings, load an example, or paste your own input.
03Inspect results
Choose settings, load an example, or paste your own input.
The display may be truncated; the exported JSON report contains all computed results.
How to interpret this
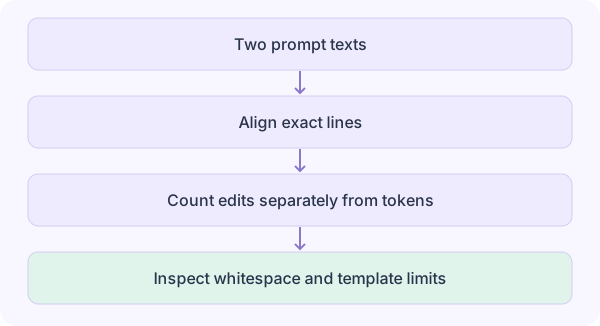
Paste versions A and B. The line-based diff preserves whitespace and highlights insertions and deletions. Token counts use the selected encoding; this is not a semantic quality evaluator. Limit: 20,000 characters and 500 lines per version.
Method references
Assumptions, implementation & acceptance
Line edits and token deltas are different quantities. Whitespace affects tokenization; a line edit is not semantic equivalence.
Reviewed counting units, statistical assumptions and numerical examples. Provider accounting and actual GPU allocation still require external measurement.
Before running: predict a boundary case
Line edits and token deltas are different quantities. Whitespace affects tokenization; a line edit is not semantic equivalence.
Hint: isolate the assumption
Keep the baseline input fixed, change one parameter or boundary, and compare both the numerical result and the claimed units. A passing example verifies this fixture only.
Minimal executable example
Save the example and linked modules in one folder. Use Node.js 22 or newer, then run node prompt-diff.mjs. npm install gpt-tokenizer@4.1.0
import {encode as rawEncode} from 'gpt-tokenizer/encoding/cl100k_base';
import {promptDiff,inspectDataset,chunkDocument,compareScores,estimateVRAM,samplingLab,speculativeLab} from './research-core.mjs';
const encode=s=>rawEncode(s,{disallowedSpecial:new Set()});
const result=promptDiff('a\nb\nc','a\nx\nc',encode);
console.log([result.inserted,result.removed,result.unchanged]); // [1,1,2]Test and transfer
Line edits and token deltas are different quantities. Whitespace affects tokenization; a line edit is not semantic equivalence.
Record input, code version, expected result and observed result in the notebook below. Then construct a counterexample that violates the assumption above and explain why the original conclusion no longer follows.
Download complete kit (.tar.gz) · Complete reference kit and regression checksPredict, test and keep evidence
Before revealing an answer, predict one result. After the exercise, record the discrepancy and a transfer test. Saved locally across language editions.
Open notebook / export / clear →The mathematical review scope is recorded per lesson. It does not establish empirical paper reproduction; report suspected errors in your notes. Review scope