Laboratorio de fragmentación RAG
Explora límites Unicode, solapamiento y recuentos reales de tokens por fragmento.
Study guide & lesson outline
LEARNING CONTRACTUnderstand → implement → investigate
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
- Understand: state assumptions, shapes/units and a counterexample.
- Implement: reproduce a numerical example and inspect boundaries.
- Investigate: compare one alternative under a matched budget.
01Configurar
02Añadir entrada
Configura los parámetros, carga un ejemplo o pega tus datos.
03Revisar resultados
Configura los parámetros, carga un ejemplo o pega tus datos.
La vista puede estar truncada; el JSON exportado incluye todos los resultados calculados.
Cómo interpretar los resultados
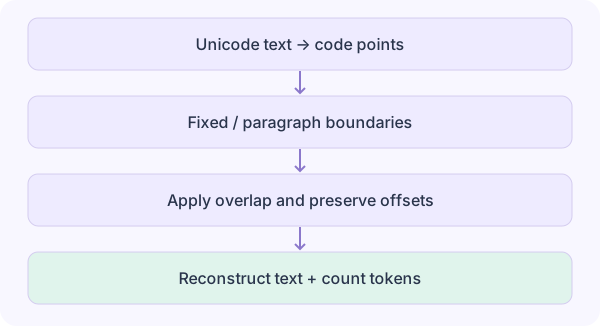
Tamaño y solapamiento se miden en puntos de código Unicode, no tokens. El modo de párrafos busca un salto de línea en la segunda mitad del fragmento. Se cuentan los tokens de cada resultado. Más solapamiento duplica texto y puede aumentar el trabajo de embeddings; no mide calidad de recuperación. Máximo: 100.000 puntos y 2.000 fragmentos.
Referencias del método
Assumptions, implementation & acceptance
Chunk size and overlap are Unicode code points, not tokens or UTF-8 bytes. Reconstruct the input without duplicating overlaps; then separately count tokens.
Reviewed counting units, statistical assumptions and numerical examples. Provider accounting and actual GPU allocation still require external measurement.
Before running: predict a boundary case
Chunk size and overlap are Unicode code points, not tokens or UTF-8 bytes. Reconstruct the input without duplicating overlaps; then separately count tokens.
Hint: isolate the assumption
Keep the baseline input fixed, change one parameter or boundary, and compare both the numerical result and the claimed units. A passing example verifies this fixture only.
Minimal executable example
Save the example and linked modules in one folder. Use Node.js 22 or newer, then run node rag-chunker.mjs. npm install gpt-tokenizer@4.1.0
import {encode as rawEncode} from 'gpt-tokenizer/encoding/cl100k_base';
import {promptDiff,inspectDataset,chunkDocument,compareScores,estimateVRAM,samplingLab,speculativeLab} from './research-core.mjs';
const encode=s=>rawEncode(s,{disallowedSpecial:new Set()});
const text='你好🌍 abc '.repeat(8);
const result=chunkDocument(text,16,5,'fixed',encode);
const rebuilt=result.chunks.map(c=>Array.from(c.text).slice(c.overlapWithPrevious).join('')).join('');
console.log(rebuilt===text); // trueTest and transfer
Chunk size and overlap are Unicode code points, not tokens or UTF-8 bytes. Reconstruct the input without duplicating overlaps; then separately count tokens.
Record input, code version, expected result and observed result in the notebook below. Then construct a counterexample that violates the assumption above and explain why the original conclusion no longer follows.
Download complete kit (.tar.gz) · Complete reference kit and regression checksPredict, test and keep evidence
Before revealing an answer, predict one result. After the exercise, record the discrepancy and a transfer test. Saved locally across language editions.
Open notebook / export / clear →The mathematical review scope is recorded per lesson. It does not establish empirical paper reproduction; report suspected errors in your notes. Review scope