ページの断片化
One extra token allocates an additional page per sequence.
ローカル計算・シミュレーション外部 API を使わないローカル教材です。合成データの結果は本番測定ではありません。
Study guide & lesson outline
LEARNING CONTRACTUnderstand → implement → investigate
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
- Understand: state assumptions, shapes/units and a counterexample.
- Implement: reproduce a numerical example and inspect boundaries.
- Investigate: compare one alternative under a matched budget.
02 · 予測と設定
技術説明、パラメータ名、解答は現在英語です。
03 · 結果を確認
方法と参考文献
32 layers, head dimension 128. Dense cache only; excludes model weights, activations, block tables and sharing. Per-sequence allocation rounds up to the next page.
Text / 原始公式
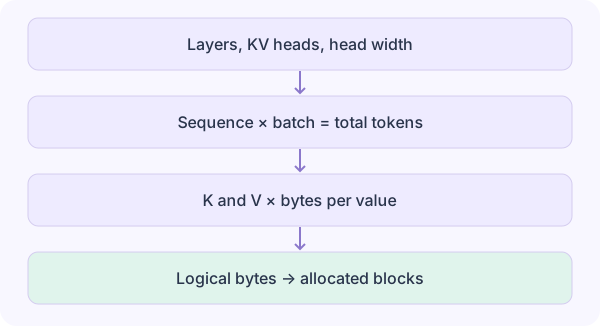
KV bytes=2×layers×KV heads×head dimension×sequence×batch×bytes/value
An estimated cache footprint is not a measured GPU throughput or total memory requirement.
GQA (2023); PagedAttention (2023) ↗練習問題
kv-5 / 01What does “Page fragmentation” test?
One extra token allocates an additional page per sequence.
Original teaching answer / local derivation. Method reference: GQA (2023); PagedAttention (2023) ↗
ラボを開く →kv-5 / 02Which computation produces the result in “Page fragmentation”?
KV
Original teaching answer / local derivation. Method reference: GQA (2023); PagedAttention (2023) ↗
ラボを開く →kv-5 / 03What is the baseline configuration for “Page fragmentation”?
{"sequence":4097,"batch":1,"heads":8,"bytes":2,"block":256}
Original teaching answer / local derivation. Method reference: GQA (2023); PagedAttention (2023) ↗
ラボを開く →kv-5 / 04What numerical result should you check for “Page fragmentation”?
{"KV cache (GiB)":0.5001220703125,"Allocated KV (GiB)":0.53125,"Padding tokens":255}
Original teaching answer / local derivation. Method reference: GQA (2023); PagedAttention (2023) ↗
ラボを開く →kv-5 / 05How would you run a controlled comparison for “Page fragmentation”?
Keep the supplied fixture and other settings fixed; change sequence. Compare logical KV GiB, allocated GiB and padding tokens.
Original teaching answer / local derivation. Method reference: GQA (2023); PagedAttention (2023) ↗
ラボを開く →kv-5 / 06What failure could invalidate a conclusion from “Page fragmentation”?
An estimated cache footprint is not a measured GPU throughput or total memory requirement.
Original teaching answer / local derivation. Method reference: GQA (2023); PagedAttention (2023) ↗
ラボを開く →kv-5 / 07Is “Page fragmentation” a benchmark of a deployed language model?
No. 32 layers, head dimension 128. Dense cache only; excludes model weights, activations, block tables and sharing. Per-sequence allocation rounds up to the next page.
Original teaching answer / local derivation. Method reference: GQA (2023); PagedAttention (2023) ↗
ラボを開く →kv-5 / 08Which evidence should you report for “Page fragmentation”?
Compare logical KV GiB, allocated GiB and padding tokens. Export inputs, engine, result and method; distinguish synthetic fixtures from observed production data.
Original teaching answer / local derivation. Method reference: GQA (2023); PagedAttention (2023) ↗
ラボを開く →kv-5 / 09How can another researcher reproduce “Page fragmentation”?
Open kv-5, reset the preset, retain the exact inputs and run. The calculation is deterministic for identical inputs.
Original teaching answer / local derivation. Method reference: GQA (2023); PagedAttention (2023) ↗
ラボを開く →kv-5 / 10What is the next validation step after “Page fragmentation”?
An estimated cache footprint is not a measured GPU throughput or total memory requirement. Test the hypothesis on a representative held-out workload and document a baseline, success metric and stopping rule before claiming deployment readiness.
Original teaching answer / local derivation. Method reference: GQA (2023); PagedAttention (2023) ↗
ラボを開く →Assumptions, implementation & acceptance
Count both K and V, KV heads rather than query heads, and sequence×batch exactly once. The byte formula excludes activations, weights, allocator fragmentation and attention workspace.
Engine formulas, scenario presets and numerical safeguards reviewed. Seeded synthetic inputs are not a production benchmark.
Before running: predict a boundary case
One extra token allocates an additional page per sequence.
Hint: isolate the assumption
Keep the baseline input fixed, change one parameter or boundary, and compare both the numerical result and the claimed units. A passing example verifies this fixture only.
Minimal executable example
Save the example and linked modules in one folder. Use Node.js 22 or newer, then run node kv-5.mjs. No third-party runtime dependencies.
import {calculate,network} from './academy-core.mjs';
const params={
  "sequence": 4097,
  "batch": 1,
  "heads": 8,
  "bytes": 2,
  "block": 256
};
const result=calculate('kv',params);
console.log(result.metrics);Test and transfer
One extra token allocates an additional page per sequence.
Record input, code version, expected result and observed result in the notebook below. Then construct a counterexample that violates the assumption above and explain why the original conclusion no longer follows.
Download complete kit (.tar.gz) · Complete reference kit and regression checksPredict, test and keep evidence
Before revealing an answer, predict one result. After the exercise, record the discrepancy and a transfer test. Saved locally across language editions.
Open notebook / export / clear →The mathematical review scope is recorded per lesson. It does not establish empirical paper reproduction; report suspected errors in your notes. Review scope