QLoRA: a memory budget is more than weight precision
Separate stored weights, computation precision, adapters and training state. Build an honest memory ledger.
QLoRA: Efficient Finetuning of Quantized LLMs · Dettmers et al. · arXiv:2305.14314
Original editorial analysis by Token Lab · Source checked 2026-10-25 · Paper claims and synthetic examples are separated.
Detailed technical articles are available in English and Chinese. This locale shows the English article with localized navigation.
01 · What the paper establishes
QLoRA combines a frozen 4-bit backbone with trainable LoRA adapters. NF4, double quantization and paged optimizers address different memory costs. The paper demonstrates large-model fine-tuning under particular hardware and training settings; the site does not run that training.
Primary source: paper abstract ↗Study guide & lesson outline
LEARNING CONTRACTUnderstand → implement → investigate
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
- Understand: state assumptions, shapes/units and a counterexample.
- Implement: reproduce a numerical example and inspect boundaries.
- Investigate: compare one alternative under a matched budget.
02 · The mechanism
Text / 原始公式
Mtotal ≈ Mbase + Mquant-metadata + Madapter
          + Mgrad + Moptimizer + Mactivation + Mworkspace
Raw base storage = parameter_count × bits / 8
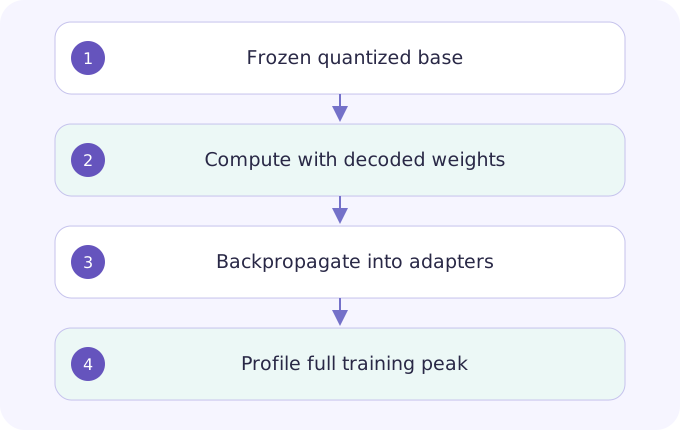
Storage precision and arithmetic precision are different contracts. A compact weight representation must be interpreted for the computation, and gradients still flow through operations to adapters. Quantization metadata also consumes memory. Paged state can help manage spikes, but moving data is not free and does not make activation memory disappear.
Notation and intuition are teaching explanations. Consult the original method for complete assumptions and implementation details.
Mechanism map & worked derivation
| Symbol | Meaning |
|---|---|
| b | Bits per stored base weight, excluding metadata |
| N | Number of base parameters |
| Mactivation | Workload-dependent saved activations |
- Start the ledger with N×b/8 bytes, then add quantization scales and other metadata. Dividing by 10⁹ gives GB; dividing by 2³⁰ gives GiB. Keep the unit explicit.
- For
×10⁹, raw 4-bit storage is 3.5 GiB. That number excludes all adapters, gradients, optimizer state and activations. - If common overhead grows from 6 to 20 GB, the 16-bit/4-bit total ratio falls from 20/9.5≈2.105 to 34/23.5≈1.447. This arithmetic explains why context length matters.
Report stored dtype and compute dtype separately. A successful forward pass does not establish that backward and optimizer steps fit.
Change one variable. Explain what moves.
Original teaching calculation, not a reproduction of the paper’s benchmark. Bars are relative within this panel; numeric values and units are authoritative.
04 · Work through an example
Original ledger: 7 billion raw weights require 14 GB at 16 bits or 3.5 GB at 4 bits, using decimal GB. Add a deliberately adjustable “other memory” budget below. With 6 GB of other memory, totals are 20 GB versus 9.5 GB: a 2.11× ratio rather than 4×. The hypothetical overhead is not a measurement of any named model.
05 · Design your experiment
Profile a small supported model at matched sequence length, microbatch and optimizer. Record allocated and reserved peak memory separately, including a complete backward/optimizer step. Compare 16-bit LoRA and quantized LoRA using the same data and adapter targets. Sweep sequence length to identify when activations dominate; record quality and throughput along with memory.
State one hypothesis; save the configuration and raw results; identify a competing explanation; report the narrowest supported conclusion. Use the linked lab as a local starting point, not a full paper reproduction.
Open related lesson / lab →06 · Limits & reviewer questions
Editorial caution: a 4-bit checkpoint is not a promise of fourfold end-to-end savings or identical task quality. Quantizer distributions, outliers, metadata, kernels and CPU paging all matter. A small synthetic memory calculator validates arithmetic, not hardware feasibility.
Why might longer contexts erase much of the relative memory advantage?
Frozen-weight storage is roughly fixed, while activations and attention-related state grow with the workload. As unchanged overhead dominates both totals, their ratio moves toward one.
07 · Read the original
NF4, double quantization and paged optimizer sections; keep their contributions separate.
Year is the first arXiv submission year. Unversioned links follow revisions; record the exact version in your reproduction report. DeepSeek-R1 here is explicitly pinned to v1.
Continue this topic
LoRA: constrain the update, not the whole model
Factor a weight update, count trainable parameters and explain the asymmetric first gradient.
Hu et al. · arXiv:2106.09685
DPO: preference learning through relative log probabilities
Derive the pairwise margin and see what β changes in a single preference example.
Rafailov et al. · arXiv:2305.18290