DPO: preference learning through relative log probabilities
Derive the pairwise margin and see what β changes in a single preference example.
Direct Preference Optimization: Your Language Model is Secretly a Reward Model · Rafailov et al. · arXiv:2305.18290
Original editorial analysis by Token Lab · Source checked 2026-10-25 · Paper claims and synthetic examples are separated.
Detailed technical articles are available in English and Chinese. This locale shows the English article with localized navigation.
01 · What the paper establishes
DPO reparameterizes a KL-regularized reward objective into a preference classification loss using a reference policy. The paper evaluates sentiment, summarization and dialogue tasks. Its objective avoids the explicit reward-model-plus-online-RL loop used in the compared setup.
Primary source: paper abstract ↗Study guide & lesson outline
LEARNING CONTRACTUnderstand → implement → investigate
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
- Understand: state assumptions, shapes/units and a counterexample.
- Implement: reproduce a numerical example and inspect boundaries.
- Investigate: compare one alternative under a matched budget.
02 · The mechanism
Text / 原始公式
Δ = log πθ(yw|x) − log πθ(yl|x)
    − log πref(yw|x) + log πref(yl|x)
L = −log σ(βΔ)
∂L/∂Δ = −βσ(−βΔ)
The margin compares how much the chosen response gains relative to the rejected one, after subtracting the reference policy’s preference. It is not merely the chosen response probability. Sequence log probabilities require consistent tokenization, masking and summation. A KL penalty in the derivation motivates staying near the reference, but a finite dataset and finite optimization do not guarantee an arbitrary hard KL ceiling.
Notation and intuition are teaching explanations. Consult the original method for complete assumptions and implementation details.
Mechanism map & worked derivation
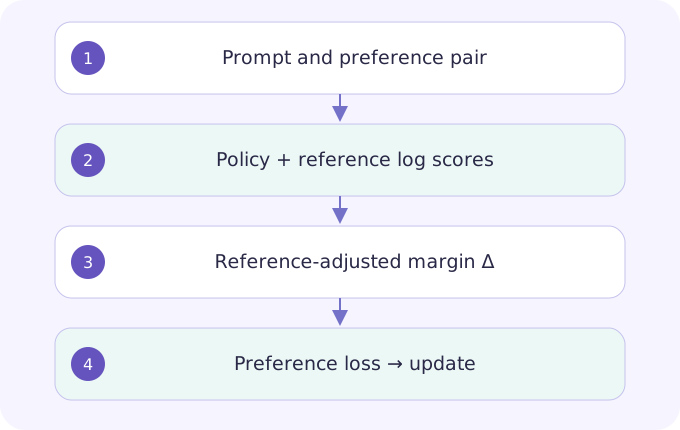
| Symbol | Meaning |
|---|---|
| yw, yl | Preferred and rejected complete responses |
| πref | Frozen reference policy |
| Δ | Policy preference log-odds minus reference log-odds |
- Compute log probabilities only for the response tokens under a consistent masking convention. Prompt-token probabilities should not accidentally alter a pairwise response comparison.
- Let policy scores be −2 and −3, reference scores −2.5 and −3.2. The policy gap is 1, the reference gap 0.7, so
At , and - Differentiate −logσ(βΔ) to obtain −βσ(−βΔ), approximately −0.708687 here. Swapping the response labels changes Δ to −0.3 and increases the loss to about 1.037488.
Assert identical-policy
Change one variable. Explain what moves.
Original teaching calculation, not a reproduction of the paper’s benchmark. Bars are relative within this panel; numeric values and units are authoritative.
04 · Work through an example
Original example: the policy log-odds are 0.8 and reference log-odds are 0.3, so
05 · Design your experiment
Create three synthetic preference pairs and manually compute the loss before training anything. Test that swapping chosen and rejected negates Δ. For a real POC, freeze the reference checkpoint, hold out prompts rather than individual responses, and compare against the supervised baseline. Track held-out preference accuracy, generation quality, length and estimated KL drift.
State one hypothesis; save the configuration and raw results; identify a competing explanation; report the narrowest supported conclusion. Use the linked lab as a local starting point, not a full paper reproduction.
Open related lesson / lab →06 · Limits & reviewer questions
Editorial caution: preference labels can encode style bias, inconsistency or distribution gaps. A decreasing training loss does not prove better factuality, safety or user utility. Sequence length can confound comparisons, so document the exact scoring convention instead of silently normalizing scores.
If policy and reference are identical, what is the loss for every pair?
Both log-ratio differences cancel, so
07 · Read the original
The KL-regularized objective, reward reparameterization and DPO loss derivation; check reference-policy terms.
Year is the first arXiv submission year. Unversioned links follow revisions; record the exact version in your reproduction report. DeepSeek-R1 here is explicitly pinned to v1.
Continue this topic
LoRA: constrain the update, not the whole model
Factor a weight update, count trainable parameters and explain the asymmetric first gradient.
Hu et al. · arXiv:2106.09685
QLoRA: a memory budget is more than weight precision
Separate stored weights, computation precision, adapters and training state. Build an honest memory ledger.
Dettmers et al. · arXiv:2305.14314