AI를 이해하세요.
읽고 실험하며 이해를 쌓아가세요.
AI 엔지니어와 연구자를 위한 학습 및 실험 공간입니다. 개념을 배우고 학습 경로를 따라 직접 검증하세요.
완전한 학습 경로
읽기 → 구현 → 평가
최신 연구 탐구
연구 아이디어를 구현과 실험으로 연결하는 엄선된 글 8편.
 추천 글
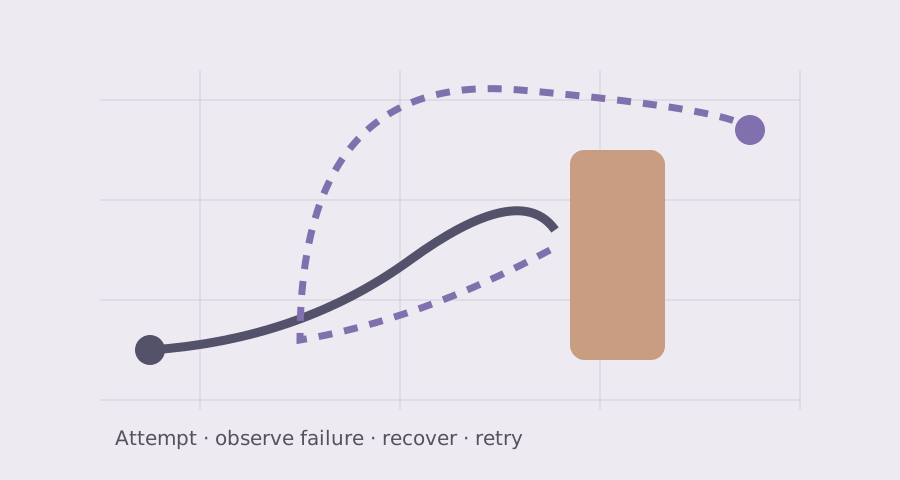
Robot recovery: when retrying helps, and when it hides failure
Posted
Read Backtrack, DexPort and ViT-H through a practical lens: frozen policies, action labels, executable motion and bounded recovery. Includes a local state-machine experiment.
 연구 노트
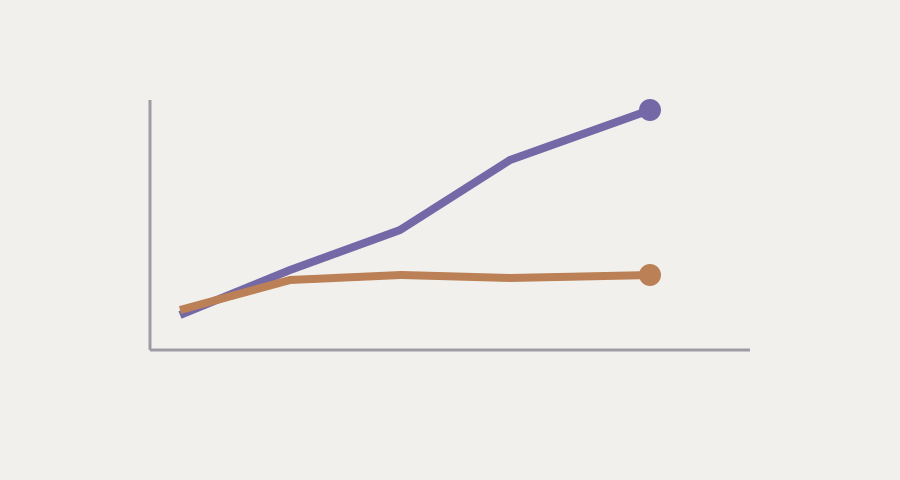
Self-improving agents: reward gains are not capability gains
Posted
A research reading guide and local experiment on adaptive harnesses, reward collapse, frozen-policy comparisons and held-out evaluation.
 연구 노트
From LLM Calls to Agent Harnesses
Posted
An English reading brief and hands-on tutorial on agent runtimes: context, tool permissions, checkpoints, bounded execution and reproducible failure tests.
 연구 노트
Test-time compute: search, verification and budgets
Posted
Prerequisites: probability, evaluation and inference cost. Learn when more attempts help and when a verifier becomes the bottleneck.
 연구 노트
Selective state spaces: Mamba and sequence memory
Posted
Prerequisites: linear algebra, recurrence and attention. Compare compressed state with explicit token retrieval.
 연구 노트
Diffusion language models: masking and iterative decoding
Posted
Prerequisites: cross-entropy, Transformers and generative modeling. Understand LLaDA-style masked generation without equating parallelism with speed.
 논문 분석
DeepSeek-R1: rewards, reasoning and what the evidence establishes
Posted
Study R1-Zero and R1 separately, then build a controlled test of reasoning improvement. This analysis is pinned to arXiv v1.
 논문 분석
LLM-as-a-judge: evaluate the evaluator
Posted
Separate answer preference from correctness and reveal how order effects can alter a reported win rate.
학습 라이브러리
학습 경로를 선택하세요.
최신 튜토리얼
학습 라이브러리에 추가된 글
Write Multi-Head Attention from scratch
Trace Q, K and V, split and merge heads, then prove your causal mask works.
튜토리얼 읽기 ↗Softmax that stays stable
Derive the gradient, work through a small example and avoid overflow.
튜토리얼 읽기 ↗K-Means beyond the happy path
Implement assignment and updates; handle empty clusters and convergence.
튜토리얼 읽기 ↗Adam, one update at a time
Understand persistent moments, bias correction and the first parameter update.
튜토리얼 읽기 ↗Beam Search without hidden mistakes
Keep global top-k candidates, track EOS and compare against greedy decoding.
튜토리얼 읽기 ↗로컬 실험
검증할 아이디어에 맞는 도구를 여세요.
입력은 브라우저에서 처리됩니다. API 키와 입력 업로드가 필요 없습니다.
면접과 프로젝트
암기보다 구현과 근거로 이해를 확인하세요.
최근 연습
면접 연습과 실습 프로젝트
Handwrite Beam Search, then defend every choice
Practice global top-k selection, EOS handling and length bias with a worked example and reference code.
연습 보기 ↗INTERVIEW / OPTIMIZATIONDerive Adam and trace the first update
A paper-and-pencil drill in moving averages and bias correction, followed by a tested implementation.
연습 보기 ↗PROJECT / TRANSFORMERSProve your KV cache is correct
Build causal attention and compare full-sequence outputs with incremental decoding using numerical invariants.
연습 보기 ↗PROJECT / RAGBuild retrieval with a measured baseline
Measure retrieval accuracy, answerable recall and correct abstention separately; inspect the failure cases.
연습 보기 ↗