GPU 메모리 추정기
실행 전에 가중치, KV 캐시, 전체 학습 상태를 분해해 봅니다.
Study guide & lesson outline
LEARNING CONTRACTUnderstand → implement → investigate
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
- Understand: state assumptions, shapes/units and a counterexample.
- Implement: reproduce a numerical example and inspect boundaries.
- Investigate: compare one alternative under a matched budget.
01설정
02입력 추가
설정 후 예제를 불러오거나 입력을 붙여 넣으세요.
03결과 확인
설정 후 예제를 불러오거나 입력을 붙여 넣으세요.
화면은 일부만 표시할 수 있으며 JSON 보고서는 전체 계산 결과를 포함합니다.
결과 해석
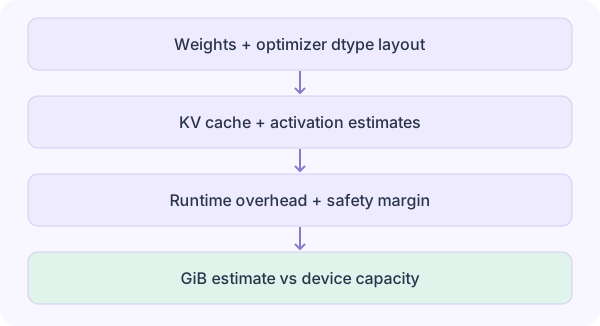
단일 장치 계획용 추정입니다. 추론은 이상적인 압축 가중치와 밀집 KV 캐시를 사용하며 양자화 메타데이터, 활성값 등에 추가 비용이 듭니다. 전체 학습은 혼합 정밀도 AdamW의 파라미터당 18바이트 기준에 지정한 여유를 더합니다. 모든 프레임워크, LoRA, 샤딩, 오프로딩, 실측 최대치를 예측하지 않습니다.
GiB = 2³⁰바이트. 학습 상태 = 파라미터 × 18바이트. KV = 2 × 레이어 × KV 헤드 × 차원 × 길이 × 동시 수 × 바이트. 안전 여유는 추가 공간을 포함한 소계에 적용됩니다.
방법 참고 자료
Assumptions, implementation & acceptance
The 18-byte training baseline is 2 working-weight + 4 master-weight + 4 gradient + 8 Adam-moment bytes per parameter. This is one dtype layout, not a universal framework constant or measured peak.
Reviewed counting units, statistical assumptions and numerical examples. Provider accounting and actual GPU allocation still require external measurement.
Before running: predict a boundary case
The 18-byte training baseline is 2 working-weight + 4 master-weight + 4 gradient + 8 Adam-moment bytes per parameter. This is one dtype layout, not a universal framework constant or measured peak.
Hint: isolate the assumption
Keep the baseline input fixed, change one parameter or boundary, and compare both the numerical result and the claimed units. A passing example verifies this fixture only.
Minimal executable example
Save the example and linked modules in one folder. Use Node.js 22 or newer, then run node vram-calculator.mjs. npm install gpt-tokenizer@4.1.0
import {encode as rawEncode} from 'gpt-tokenizer/encoding/cl100k_base';
import {promptDiff,inspectDataset,chunkDocument,compareScores,estimateVRAM,samplingLab,speculativeLab} from './research-core.mjs';
const encode=s=>rawEncode(s,{disallowedSpecial:new Set()});
const result=estimateVRAM({mode:'inference',params:7,weightBits:16,layers:32,kvHeads:8,headDim:128,sequence:4096,batch:1,kvBytes:2,runtime:2,activation:4,margin:15,capacity:24});
console.log(result.components.cache); // 0.5 GiBTest and transfer
The 18-byte training baseline is 2 working-weight + 4 master-weight + 4 gradient + 8 Adam-moment bytes per parameter. This is one dtype layout, not a universal framework constant or measured peak.
Record input, code version, expected result and observed result in the notebook below. Then construct a counterexample that violates the assumption above and explain why the original conclusion no longer follows.
Download complete kit (.tar.gz) · Complete reference kit and regression checksPredict, test and keep evidence
Before revealing an answer, predict one result. After the exercise, record the discrepancy and a transfer test. Saved locally across language editions.
Open notebook / export / clear →The mathematical review scope is recorded per lesson. It does not establish empirical paper reproduction; report suspected errors in your notes. Review scope