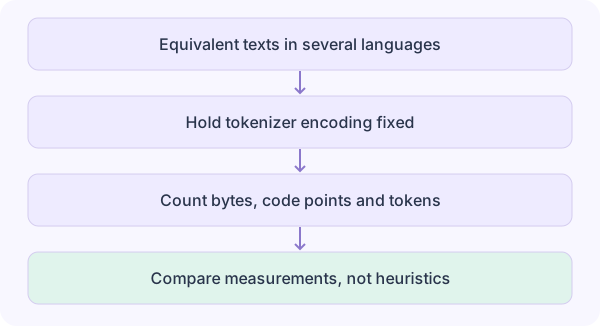
Hold encoding and text fixed. Record UTF-8 bytes, code points and tokens separately; the English 4-characters-per-token rule is not a multilingual formula.
Shared code, English mathematical explanation and key multilingual numeric passages reviewed. This is not a full translation proofread.
Mechanism map: follow the transformations from top to bottom.
Before running: predict a boundary case
Hold encoding and text fixed. Record UTF-8 bytes, code points and tokens separately; the English 4-characters-per-token rule is not a multilingual formula.
Hint: isolate the assumption
Keep the baseline input fixed, change one parameter or boundary, and compare both the numerical result and the claimed units. A passing example verifies this fixture only.
Minimal executable example
Save the example and linked modules in one folder. Use Node.js 22 or newer, then run node multilingual-tokenization.mjs. npm install gpt-tokenizer@4.1.0
import { encode } from 'gpt-tokenizer/encoding/cl100k_base';
// npm install gpt-tokenizer@4.1.0
const samples = [
'Hello, world!', '你好,世界!',
'¡Hola, mundo!', 'こんにちは、世界!',
'안녕하세요, 세계!', '👨👩👧👦'
];
for (const text of samples) {
const ids = encode(text);
console.log(text, ids.length);
}
Hold encoding and text fixed. Record UTF-8 bytes, code points and tokens separately; the English 4-characters-per-token rule is not a multilingual formula.
Record input, code version, expected result and observed result in the notebook below. Then construct a counterexample that violates the assumption above and explain why the original conclusion no longer follows.
Before revealing an answer, predict one result. After the exercise, record the discrepancy and a transfer test. Saved locally across language editions.
The mathematical review scope is recorded per lesson. It does not establish empirical paper reproduction; report suspected errors in your notes. Review scope