1. Why can harder negatives be harmful?
참고 답변과 평가 기준
They may be false negatives or annotation errors. High probability gives them substantial repulsive gradient.
Inspect InfoNCE, temperature and the exact gradient applied to a possible false negative.
로컬 계산과 합성 예제입니다. 유료 API나 실제 모델 벤치마크를 사용하지 않습니다.기술 본문은 영어와 중국어로 제공됩니다. 이 언어에서는 영어 기술 본문을 표시합니다.
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
사전 지식 · Softmax, cross-entropy, derivatives.
The positive is pulled up in similarity while negatives are pushed down by gradient descent. A high-scoring negative gets a stronger push. If that negative is actually relevant, the training signal conflicts with the desired semantics.
L = −log[exp(s₊/τ) / Σⱼ exp(sⱼ/τ)]
∂L/∂sᵢ = (pᵢ − 1[i=positive]) / τ
positive index is zero-based; excluded candidates leave the denominator
Common pitfall: Removing candidates makes the classification task easier; reduced loss alone does not prove improved representation learning.
With 3 equal similarity scores and one positive, what is InfoNCE loss in nats?
−ln(1/3) = ln(3) ≈ 1.098612
Treat index 1 as a known false negative. Run with all candidates, then exclude index 1 and compare its gradient and the positive probability. Sweep temperature 0.05, 0.2 and 1.
Deliver: input configurations, exported results, controlled variables, observations, alternative explanations and the next validation step.
Removing a candidate changes task difficulty. A lower loss after removal cannot establish improved embeddings; evaluate a fixed held-out retrieval task.
실행하면 결과가 표시됩니다.
변수를 통제하여 결과를 비교하세요. 내보내기에는 입력과 방법이 포함됩니다.
자기 평가: 원리와 가정을 설명하고 구별 가능한 실험을 제안하세요. LLM 자동 채점은 없습니다.
They may be false negatives or annotation errors. High probability gives them substantial repulsive gradient.
No. The 1/τ factor grows, but softmax probabilities also change and can saturate. Inspect both terms.
Keep encoder, data budget and evaluation fixed, audit negative labels, compare multiple seeds and measure held-out retrieval rather than only training loss.
Exact single-anchor loss and score gradients with supplied similarities; no encoder is trained. The tool cannot identify false negatives automatically. Compare retrieval quality using a separate dataset.
arXiv:1807.03748 · 2018
van den Oord, Li & Vinyals · Year denotes first arXiv submission
Read: Section 2.3: InfoNCE; Appendix A.1: mutual-information argument.
Reading checkpoint: Track the negative-sampling assumptions before interpreting a mutual-information bound.
@misc{arxiv180703748,
  title = {Representation Learning with Contrastive Predictive Coding},
  year = {2018},
  eprint = {1807.03748},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/1807.03748}
}
arXiv:2002.05709 · 2020
Chen et al. · Year denotes first arXiv submission
Read: Framework, augmentation ablations, projection head and contrastive objective.
Reading checkpoint: List which augmentation invariances are useful or harmful for your domain. A lower training loss is not the only evaluation.
@misc{arxiv200205709,
  title = {A Simple Framework for Contrastive Learning of Visual Representations},
  year = {2020},
  eprint = {2002.05709},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2002.05709}
}Exact single-anchor loss and score gradients with supplied similarities; no encoder is trained. The tool cannot identify false negatives automatically. Compare retrieval quality using a separate dataset.
Objective, derivatives, worked examples and implementation reviewed. A passing finite-difference or manifest check is not a paper reproduction certificate.
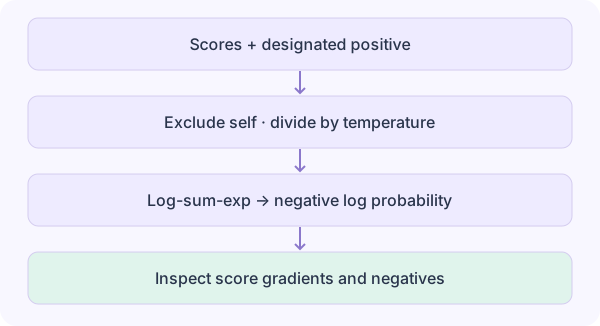
Treat index 1 as a known false negative. Run with all candidates, then exclude index 1 and compare its gradient and the positive probability. Sweep temperature 0.05, 0.2 and 1.
Keep the baseline input fixed, change one parameter or boundary, and compare both the numerical result and the claimed units. A passing example verifies this fixture only.
Save the example and linked modules in one folder. Use Node.js 22 or newer, then run node contrastive-learning.mjs. No third-party runtime dependencies.
import {runPhd} from './phd-core.mjs';
const params={
  "scores": "0.8,0.75,0.2,-0.1",
  "positive": 0,
  "temperature": 0.2,
  "exclude": -1
};
console.log(runPhd('contrastive-learning',params));Treat index 1 as a known false negative. Run with all candidates, then exclude index 1 and compare its gradient and the positive probability. Sweep temperature 0.05, 0.2 and 1.
Record input, code version, expected result and observed result in the notebook below. Then construct a counterexample that violates the assumption above and explain why the original conclusion no longer follows.
Download complete kit (.tar.gz) · Complete reference kit and regression checksBefore revealing an answer, predict one result. After the exercise, record the discrepancy and a transfer test. Saved locally across language editions.
Open notebook / export / clear →The mathematical review scope is recorded per lesson. It does not establish empirical paper reproduction; report suspected errors in your notes. Review scope