1. Why check before clipping?
참고 답변과 평가 기준
The numerical derivative is of the loss; clipping transforms the update and no longer equals that derivative.
Check gradients numerically, inject a reduction bug, and distinguish instability from a wrong derivative.
로컬 계산과 합성 예제입니다. 유료 API나 실제 모델 벤치마크를 사용하지 않습니다.기술 본문은 영어와 중국어로 제공됩니다. 이 언어에서는 영어 기술 본문을 표시합니다.
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
사전 지식 · Chain rule, mean squared error, vector norms.
Finite differences test whether your derivative matches the declared objective. Compare raw gradients before clipping; clipping intentionally changes the update. A sum gradient is 32 times the mean gradient on this 32-row fixture.
L = Σ(wxᵢ+b−yᵢ)²/(2n)
∂L/∂w = mean[(wxᵢ+b−yᵢ)xᵢ]
g_FD = [L(θ+ε)−L(θ−ε)]/(2ε)
relative error = ||g−g_FD|| / max(10⁻¹², ||g||+||g_FD||)
Common pitfall: Decreasing loss can coexist with a wrong reduction. Do not equate numerical stability with correct implementation.
At
mean[(-2)×1,(-4)×2] = -5
Run the baseline; enable the reduction bug; then disable it and set input scale to 20. Find a learning rate that restores stable training. Compare exports with one variable changed.
Deliver: input configurations, exported results, controlled variables, observations, alternative explanations and the next validation step.
The Hessian in w scales with mean(x²). A stable learning rate at scale 1 may be too large at scale 20. Clipping can stabilize updates but cannot repair the wrong derivative.
실행하면 결과가 표시됩니다.
변수를 통제하여 결과를 비교하세요. 내보내기에는 입력과 방법이 포함됩니다.
자기 평가: 원리와 가정을 설명하고 구별 가능한 실험을 제안하세요. LLM 자동 채점은 없습니다.
The numerical derivative is of the loss; clipping transforms the update and no longer equals that derivative.
No. A constant gradient scaling can mimic a different learning rate. Check objective reduction, parameter paths and precision.
Overfit a tiny batch, verify targets, run finite differences, inspect gradient norms, then vary input scale and step size independently.
Synthetic linear regression, not a deep-network profiler. Training stops if loss exceeds 10¹². Finite-difference checks are local and do not prove every gradient is correct.
arXiv:1412.6980 · 2014
Kingma & Ba · Year denotes first arXiv submission
Read: Algorithm 1; moment estimates and bias correction.
Reading checkpoint: Explain why zero-initialized moments need correction. The gradient debugger uses SGD, not Adam.
@misc{arxiv14126980,
  title = {Adam: A Method for Stochastic Optimization},
  year = {2014},
  eprint = {1412.6980},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/1412.6980}
}
arXiv:1711.05101 · 2017
Loshchilov & Hutter · Year denotes first arXiv submission
Read: Comparison of L2 regularization and decoupled decay under adaptive updates.
Reading checkpoint: Write the two updates side by side; identify where the preconditioner acts. This is a reading extension, not an implemented AdamW benchmark.
@misc{arxiv171105101,
  title = {Decoupled Weight Decay Regularization},
  year = {2017},
  eprint = {1711.05101},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/1711.05101}
}Synthetic linear regression, not a deep-network profiler. Training stops if loss exceeds 10¹². Finite-difference checks are local and do not prove every gradient is correct.
Objective, derivatives, worked examples and implementation reviewed. A passing finite-difference or manifest check is not a paper reproduction certificate.
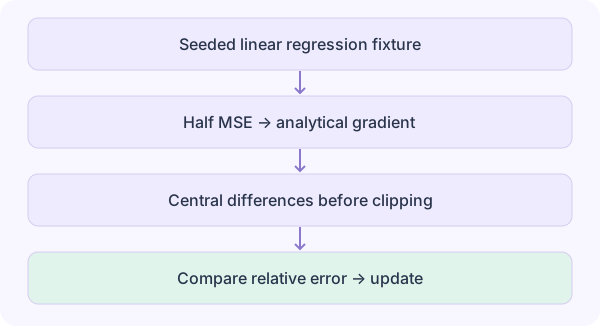
Run the baseline; enable the reduction bug; then disable it and set input scale to 20. Find a learning rate that restores stable training. Compare exports with one variable changed.
Keep the baseline input fixed, change one parameter or boundary, and compare both the numerical result and the claimed units. A passing example verifies this fixture only.
Save the example and linked modules in one folder. Use Node.js 22 or newer, then run node gradient-debugger.mjs. No third-party runtime dependencies.
import {runPhd} from './phd-core.mjs';
const params={
  "rate": 0.1,
  "scale": 1,
  "clip": 0,
  "bug": 0,
  "epochs": 100,
  "seed": 42
};
console.log(runPhd('gradient-debugger',params));Run the baseline; enable the reduction bug; then disable it and set input scale to 20. Find a learning rate that restores stable training. Compare exports with one variable changed.
Record input, code version, expected result and observed result in the notebook below. Then construct a counterexample that violates the assumption above and explain why the original conclusion no longer follows.
Download complete kit (.tar.gz) · Complete reference kit and regression checksBefore revealing an answer, predict one result. After the exercise, record the discrepancy and a transfer test. Saved locally across language editions.
Open notebook / export / clear →The mathematical review scope is recorded per lesson. It does not establish empirical paper reproduction; report suspected errors in your notes. Review scope