1. Why can LoRA start with a zero update without getting stuck?
참고 답변과 평가 기준
Make one factor zero and the other nonzero. Their product is zero, but the zero factor can receive a nonzero gradient.
Train low-rank factors, compare an analytical capacity bound, and inspect initialization failure.
로컬 계산과 합성 예제입니다. 유료 API나 실제 모델 벤치마크를 사용하지 않습니다.기술 본문은 영어와 중국어로 제공됩니다. 이 언어에서는 영어 기술 본문을 표시합니다.
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
사전 지식 · Matrix multiplication, rank, singular values, gradients.
A low-rank update restricts the space of possible changes. The experiment fits a known 8×8 target with singular values [5,3,1,0.3,0,0,0,0]. The rank-r optimum has loss equal to the sum of discarded squared singular values divided by 128.
ΔW = BA; A∈R^(r×d), B∈R^(d×r)
trainable parameters = 2dr (vs d²)
L = ||BA−T||²_F / (2×8²)
∇B = (BA−T)Aᵀ/64; ∇A = Bᵀ(BA−T)/64
Common pitfall: Equal optimizer steps across ranks do not imply equal FLOPs; low matrix reconstruction loss does not establish downstream language-model quality.
For a 4096×4096 layer and rank 8, how many parameters are in A and B together?
4096×8 + 8×4096 = 65,536; 0.390625% of 4096²
Compare rank 1,2,4 with identical seed and steps. Then initialize both factors to zero. Separate the theoretical rank limit from failure to reach that limit during optimization.
Deliver: input configurations, exported results, controlled variables, observations, alternative explanations and the next validation step.
If both A and B are zero, both gradients are zero. Random A with zero B gives a zero initial update but a nonzero first gradient for B.
실행하면 결과가 표시됩니다.
변수를 통제하여 결과를 비교하세요. 내보내기에는 입력과 방법이 포함됩니다.
자기 평가: 원리와 가정을 설명하고 구별 가능한 실험을 제안하세요. LLM 자동 채점은 없습니다.
Make one factor zero and the other nonzero. Their product is zero, but the zero factor can receive a nonzero gradient.
Not alone. Compare compute, parameter budget, tuning budget and uncertainty; capacity and optimization can both change.
It isolates representational limits for this known matrix. A remaining gap may reflect optimization, and does not predict LLM task quality.
Actual local matrix optimization, not fine-tuning a language model. Frozen base
arXiv:2106.09685 · 2021
Hu et al. · Year denotes first arXiv submission
Read: Low-rank parameterization, initialization and rank investigations.
Reading checkpoint: Derive parameter count and the first update when B=0; distinguish the toy matrix experiment from language-model fine-tuning.
@misc{arxiv210609685,
  title = {LoRA: Low-Rank Adaptation of Large Language Models},
  year = {2021},
  eprint = {2106.09685},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2106.09685}
}
arXiv:2305.14314 · 2023
Dettmers et al. · Year denotes first arXiv submission
Read: Frozen quantized backbone, NF4, double quantization and paged optimizers.
Reading checkpoint: Make separate memory accounts for weights, adapters, optimizer states and activations. The site does not execute QLoRA.
@misc{arxiv230514314,
  title = {QLoRA: Efficient Finetuning of Quantized LLMs},
  year = {2023},
  eprint = {2305.14314},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2305.14314}
}Actual local matrix optimization, not fine-tuning a language model. Frozen base
Objective, derivatives, worked examples and implementation reviewed. A passing finite-difference or manifest check is not a paper reproduction certificate.
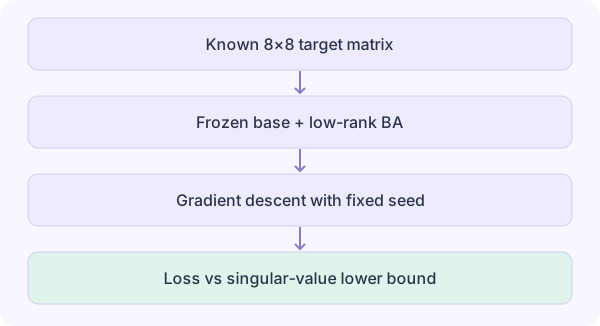
Compare rank 1,2,4 with identical seed and steps. Then initialize both factors to zero. Separate the theoretical rank limit from failure to reach that limit during optimization.
Keep the baseline input fixed, change one parameter or boundary, and compare both the numerical result and the claimed units. A passing example verifies this fixture only.
Save the example and linked modules in one folder. Use Node.js 22 or newer, then run node lora-rank.mjs. No third-party runtime dependencies.
import {runPhd} from './phd-core.mjs';
const params={
  "rank": 2,
  "rate": 0.8,
  "epochs": 1000,
  "seed": 42,
  "dimension": 4096,
  "zeroBoth": 0
};
console.log(runPhd('lora-rank',params));Compare rank 1,2,4 with identical seed and steps. Then initialize both factors to zero. Separate the theoretical rank limit from failure to reach that limit during optimization.
Record input, code version, expected result and observed result in the notebook below. Then construct a counterexample that violates the assumption above and explain why the original conclusion no longer follows.
Download complete kit (.tar.gz) · Complete reference kit and regression checksBefore revealing an answer, predict one result. After the exercise, record the discrepancy and a transfer test. Saved locally across language editions.
Open notebook / export / clear →The mathematical review scope is recorded per lesson. It does not establish empirical paper reproduction; report suspected errors in your notes. Review scope