Deep RL that Matters: a score is a distribution
Separate seed variation, implementation choices and model selection before declaring an improvement.
Deep Reinforcement Learning that Matters · Henderson et al. · arXiv:1709.06560
Original editorial analysis by Token Lab · Source checked 2026-10-25 · Paper claims and synthetic examples are separated.
01 · What the paper establishes
The paper investigates variability and reproducibility in deep reinforcement learning and recommends more careful experimental reporting. It demonstrates why baselines and uncertainty matter. Its numerical RL findings should not be transplanted directly into LLM experiments.
Primary source: paper abstract ↗Study guide & lesson outline
LEARNING CONTRACTUnderstand → implement → investigate
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
- Understand: state assumptions, shapes/units and a counterexample.
- Implement: reproduce a numerical example and inspect boundaries.
- Investigate: compare one alternative under a matched budget.
02 · The mechanism
Text / 原始公式
Mean effect = mean(Bᵢ−Aᵢ)
SE ≈ s/√n for independent observations
Var(B−A)=Var(B)+Var(A)−2Cov(A,B)
Pairing is a study-design decision, not a file-format trick.
Randomness is not a nuisance that disappears when one seed is fixed. It is part of the population over which a claim may need to generalize. More independent runs reduce uncertainty about a mean, but cannot repair a biased evaluation protocol. Pairing can reduce variance when the pairing has a defensible scientific meaning.
Notation and intuition are teaching explanations. Consult the original method for complete assumptions and implementation details.
Mechanism map & worked derivation
| Symbol | Meaning |
|---|---|
| Scientifically matched pair difference | |
| s_d | Sample standard deviation of differences |
| n | Independent pairs, not repeated calls on one item |
- Use differences [1,2,3]. Their mean is 2 and sample standard deviation is 1. The estimated standard error is 1/√3≈0.577350.
- Multiplying by 1.96 gives an illustrative normal half-width 1.131607. With only three pairs and unknown variance, that normal approximation is weak; do not report it as a reliable small-sample interval.
- Bootstrapping should resample whole independent units. If several rows belong to one task or user, consider cluster-level resampling rather than pretending rows are independent.
A small interval can coexist with a biased experiment. Check leakage, selection and tuning budgets separately.
Change one variable. Explain what moves.
Original teaching calculation, not a reproduction of the paper’s benchmark. Bars are relative within this panel; numeric values and units are authoritative.
04 · Work through an example
Original illustration: assume independent normally distributed run scores with observed standard deviation 10. The rough normal 95% half-width 1.96s/√n is 9.8 at
05 · Design your experiment
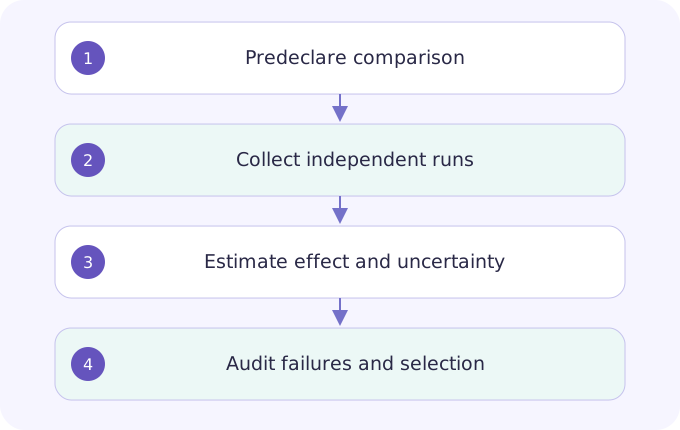
Predeclare the metric, run budget and stopping rule. Keep code, environment, dataset and evaluation horizon fixed across methods. Run multiple seeds and preserve raw per-run results, failures and exclusions. Compare an effect-size interval against a practical threshold, and audit whether tuning effort favored one baseline.
State one hypothesis; save the configuration and raw results; identify a competing explanation; report the narrowest supported conclusion. Use the linked lab as a local starting point, not a full paper reproduction.
Open related lesson / lab →06 · Limits & reviewer questions
Editorial caution: more seeds do not correct data leakage, environment bugs or cherry-picked tasks. Repeatedly checking significance and stopping on a favorable result changes the procedure. A reproducible negative result can be more useful than an unexplained winning seed.
What is wrong with reporting only the best of ten seeds for both methods?
It describes a selected extreme rather than typical performance. Variance itself affects the selected maximum, and the selection cost is hidden unless the full distribution and budget are reported.
07 · Read the original
Sources of variation, baseline comparisons and reporting recommendations.
Year is the first arXiv submission year. Unversioned links follow revisions; record the exact version in your reproduction report. DeepSeek-R1 here is explicitly pinned to v1.
Continue this topic
Calibration: being right is different from knowing how often
Adjust temperature without changing class ranking, and learn why one confidence score cannot establish calibration.
Guo et al. · arXiv:1706.04599
Show Your Work: compare search budgets, not just winners
A better winning score can come from more attempts. Plot the selection process as part of the result.
Dodge et al. · arXiv:1909.03004
LLM-as-a-judge: evaluate the evaluator
Separate answer preference from correctness and reveal how order effects can alter a reported win rate.
Zheng et al. · arXiv:2306.05685