SFT → RLHF → DPO: different training signals
Choose the signal that matches the available feedback.
Study guide & lesson outline
LEARNING CONTRACTUnderstand → implement → investigate
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
- Understand: state assumptions, shapes/units and a counterexample.
- Implement: reproduce a numerical example and inspect boundaries.
- Investigate: compare one alternative under a matched budget.
Understand the mechanism
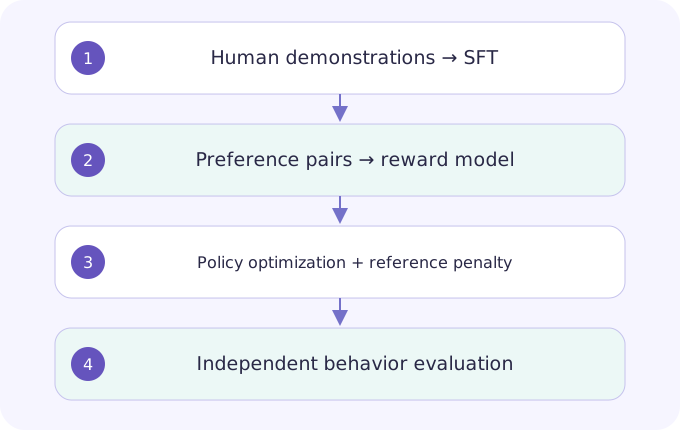
SFT learns from demonstrations of desired outputs. A common RLHF pipeline fits a reward model from preferences and optimizes a policy with a reference penalty. DPO instead uses pairwise preferences and reference log probabilities directly in its loss. DPO is preference optimization, not an online environment-interaction loop simply because it is related to an RL objective.
Text / 原始公式
SFT: −log πθ(y_demo|x)
RLHF: E[rφ(x,y)]−β KL(πθ||πref)
DPO: −log σ(βΔ_log-ratio)
Mechanism map & worked derivation
| Symbol | Meaning |
|---|---|
| rφ | Learned reward proxy |
| πref | Reference policy for the drift penalty |
| β | Trade-off coefficient under the stated convention |
- Distinguish three data products: demonstrations for SFT, comparisons for reward learning, and sampled trajectories for policy optimization. They are not interchangeable labels.
- For two policies on the same prompt distribution, (expected reward, expected KL)=(1,0.4) and (0.8,0.1),
gives regularized values 0.6 and 0.7. A lower raw reward can win after the drift penalty. - Evaluate the selected policy with independent task labels and blinded human comparisons. Otherwise reward-model errors can become both the training target and the apparent success criterion.
Report who labeled the data and which prompt distribution was evaluated. A single reward score cannot represent every user objective.
Original exercise & analysis
Use the same held-out prompts to compare a base model, SFT checkpoint and preference-tuned checkpoint. Control generation settings and response length. Audit helpfulness, factuality and refusal separately; a single overall preference score can hide regressions.
Human preference is neither a perfect truth label nor a universal representation of all users.
Can RLHF improve behavior without increasing parameter count?
Yes. Optimization changes the distribution of outputs under the model. That is a change in behavior on an evaluation distribution, not evidence that every capability improved.