Learn what a token represents, inspect a real encoding, and verify a lossless round trip.
A token is not a word
A language model receives token IDs rather than a string of words. A tokenizer maps text to those integers using a vocabulary and encoding rules. A common word can be one token; an unfamiliar name may be several. Spaces, punctuation, and newlines also matter.
Byte Pair Encoding (BPE) builds useful subword units through learned merge rules. The visible fragments are a debugging aid, not a linguistic segmentation of the sentence.
Study guide & lesson outlineLEARNING CONTRACT
Understand → implement → investigate
Goal: explain the mechanism in this lesson, reproduce one example and test a failure case. Reading alone does not mark mastery.
Understand: state assumptions, shapes/units and a counterexample.
Implement: reproduce a numerical example and inspect boundaries.
Investigate: compare one alternative under a matched budget.
Run a reproducible example
Choose cl100k_base and enter Hello, world! exactly, including the comma and space. The result is four IDs: 9906, 11, 1917, 0. Select each colored token to inspect its fragment. Then remove the comma or change capitalization and compare the sequence.
Switching to o200k_base changes the vocabulary and may change IDs or counts. An ID only has meaning with its encoding. Keep both the encoding name and IDs when exporting a result.
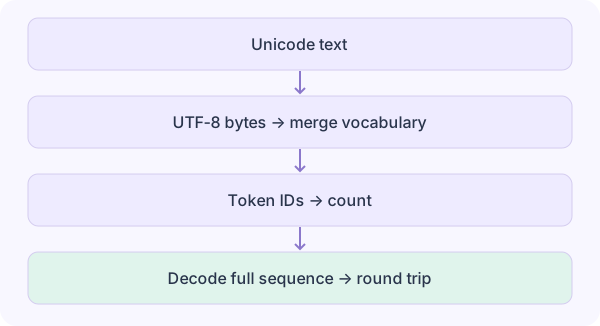
Decode the entire sequence and compare it with the original text. A single token may split a UTF-8 character and display a replacement character on its own, even when the full sequence decodes correctly.
This tool counts encoded text. It does not reproduce an entire API request: role markers, tool definitions, media, and other service-specific fields may add usage. Compare your local estimate with the API response before using it for billing or hard limits.
Round-trip decode(encode(text)) equals the original text. Individual tokens may split UTF-8 sequences; do not require each token to decode independently.
Shared code, English mathematical explanation and key multilingual numeric passages reviewed. This is not a full translation proofread.
Mechanism map: follow the transformations from top to bottom.
Before running: predict a boundary case
Round-trip decode(encode(text)) equals the original text. Individual tokens may split UTF-8 sequences; do not require each token to decode independently.
Hint: isolate the assumption
Keep the baseline input fixed, change one parameter or boundary, and compare both the numerical result and the claimed units. A passing example verifies this fixture only.
Minimal executable example
Save the example and linked modules in one folder. Use Node.js 22 or newer, then run node tokens-and-tokenizers.mjs. npm install gpt-tokenizer@4.1.0
Round-trip decode(encode(text)) equals the original text. Individual tokens may split UTF-8 sequences; do not require each token to decode independently.
Record input, code version, expected result and observed result in the notebook below. Then construct a counterexample that violates the assumption above and explain why the original conclusion no longer follows.
Before revealing an answer, predict one result. After the exercise, record the discrepancy and a transfer test. Saved locally across language editions.
The mathematical review scope is recorded per lesson. It does not establish empirical paper reproduction; report suspected errors in your notes. Review scope